Learn how to create positive and negative test cases, understand the differences between them, and use practical examples to improve test coverage.
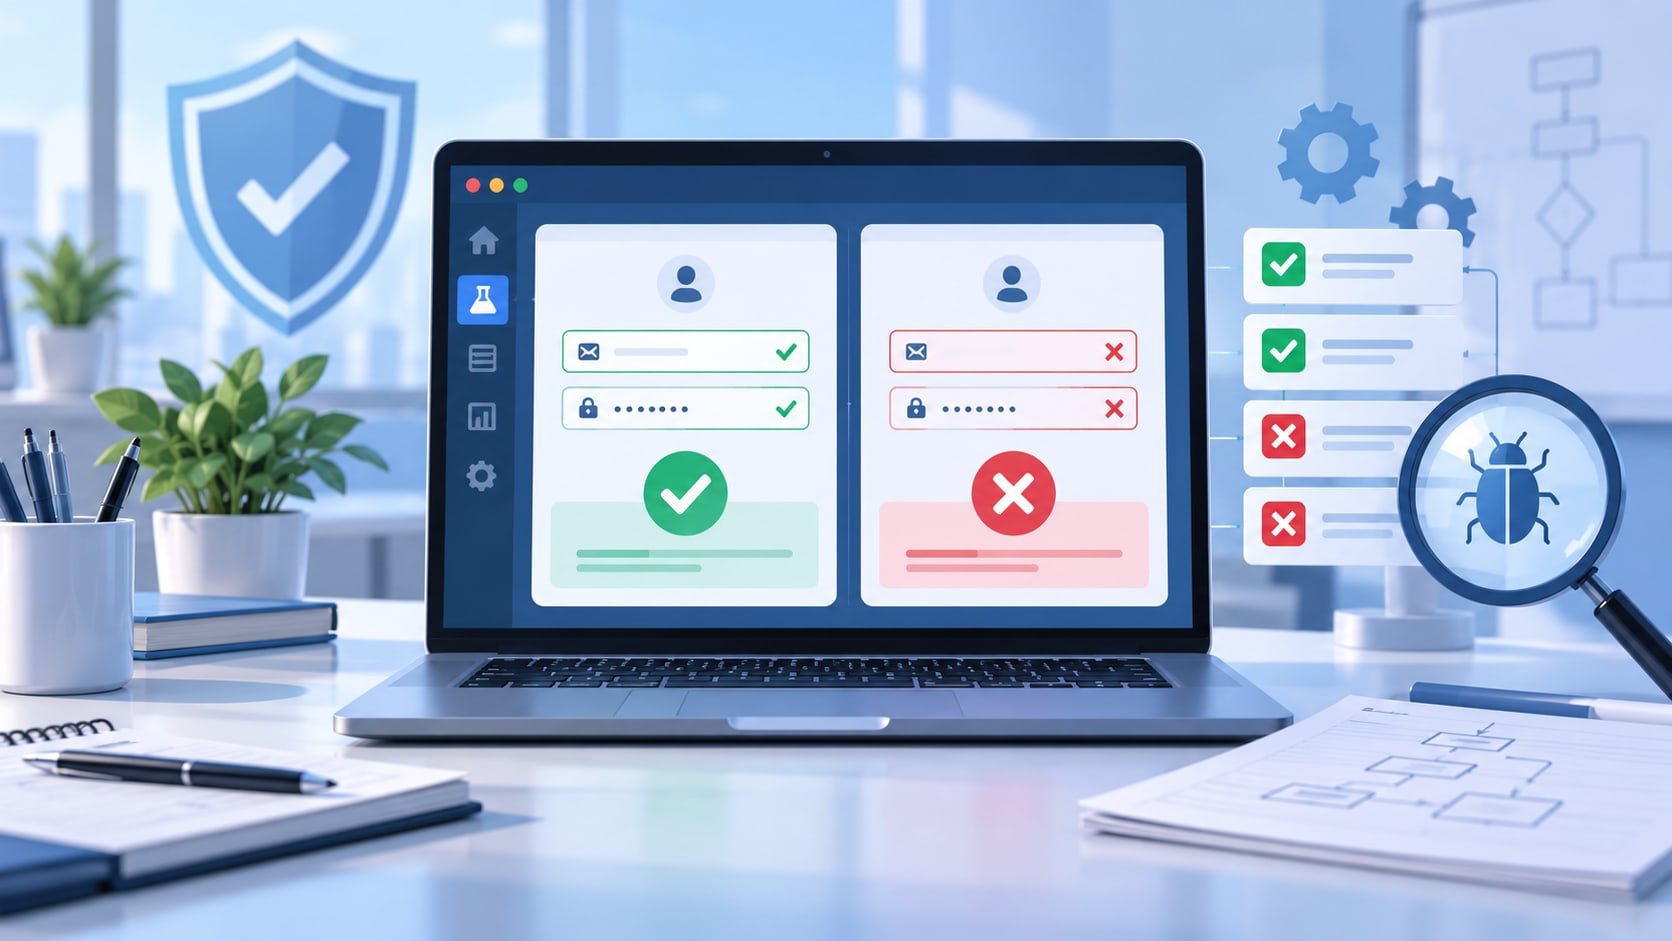
Any feature can be checked from two directions: by confirming it works with valid input, and by observing how it responds when the input is wrong. Those two directions produce positive test cases and negative test cases, and a suite built around the first direction alone passes cleanly while users still break the product. For that reason, teams that write test cases for both paths find defects in validation and error handling before release.
The distinction matters most during test design, when you decide how much effort each path deserves. The sections below cover the difference between the two types and the techniques behind each one, followed by the best practices that keep the suite maintainable as the product grows.
What Are Positive and Negative Test Cases?
Positive test cases confirm that a feature behaves as specified when it receives valid data under expected conditions. Negative test cases, in contrast, confirm that the system rejects invalid data and returns a clear error while keeping stored records intact.
A registration form makes the difference concrete. One case submits a correctly formed email address and expects a created account, while another submits an address with no domain and expects a validation message and no account. The comparison below summarizes where the two types diverge.
| Aspect | Positive test cases | Negative test cases |
|---|---|---|
| Purpose | Confirm specified behavior works | Confirm invalid input is handled safely |
| Input data | Valid, within accepted ranges | Invalid, empty, oversized, or malformed |
| Expected result | Successful operation and correct output | Controlled rejection with a clear error message |
| Main source | Acceptance criteria and user stories | Business rules, field constraints, and security requirements |
| Typical volume | One or two per acceptance criterion | Several per constraint, one per invalid class |
| What a failure signals | Broken core functionality | Weak validation or missing error handling |
Structurally the two are identical, since both follow the same format, with preconditions before the steps and a documented expected result. The difference therefore sits in the data you select and the outcome you record.
Why Create Both Positive and Negative Test Cases?
A suite of only positive test cases proves that the feature works when users behave as the specification assumes. In practice, someone will paste text into a number field or lose connection mid-payment, so the code paths handling those events need coverage of their own.
Negative test cases also carry most of the security value in functional testing. Input validation flaws such as SQL injection and buffer overflow appear when the application accepts data it should refuse. Auditors in regulated sectors look for the same evidence, because a documented rejection path shows that a control exists and was verified.
How to Create Positive Test Cases
Start from the acceptance criteria, since each criterion describes behavior someone has agreed to deliver. Before you create positive test case steps, confirm that the criterion is testable and that the expected output is stated in measurable terms.
From there, select representative valid data and leave edge values to the negative side, keeping one behavior per case so a failure points to one cause. Write the expected result as an observable outcome, such as a confirmation screen with an order number, and list the preconditions that have to hold before step one. Where the specification is already written down, AI test case creating tools can draft the valid-path steps from a user story, leaving your team to review the data choices and expected results.
How to Create Negative Test Cases
To create negative test case coverage systematically, apply established design techniques across the inputs a feature accepts. Equivalence partitioning identifies classes of invalid data, while boundary value analysis targets the values immediately outside the accepted range, such as one below the minimum. Working through the categories below then gives predictable coverage for a form or an API endpoint.
- Empty submissions and fields containing only whitespace
- Values one unit outside a documented boundary
- Wrong data types, such as letters in a numeric amount field
- Input longer than the field limit, including multibyte characters
- Special characters and script fragments in free-text fields
- Duplicate submissions from a double click or a repeated API call
- Actions attempted with an expired session or an insufficient role
- Interrupted operations, such as a connection dropped mid-transaction
For each category, document the expected error message and the expected state of the data afterward. A case that stops at "an error appears" cannot detect a partial write, which is an expensive defect to find in production.
How to Create Positive and Negative Test Cases from Requirements
Requirements convert into cases through a simple mapping: a functional requirement yields at least one positive case, while the constraints inside it yield one or more negative cases. Reading those constraints separately from the behavior keeps the negative side from being forgotten under deadline pressure.
Consider a requirement stating that a customer may transfer up to 5,000 per day. The positive case transfers 4,999 and expects success, while negative cases attempt 5,001 and a second transfer that pushes the daily total over the limit. Linking each case back to its requirement in a traceability matrix then shows which rules have no negative coverage yet.
Best Practices for Creating Positive and Negative Test Cases
Most of the maintenance effort in a mixed suite falls on the negative cases, so the practices below focus there.
- Prioritize by risk before volume. Negative combinations multiply quickly, so rank fields by what a failure would cost, then cover payment and authentication inputs exhaustively while sampling low-risk cosmetic fields.
- Keep the expected result specific enough to fail. State the exact message or status code the system should return, because a vague expectation lets a tester mark a broken path as passed.
- Reuse steps across cases. Shared preconditions such as login belong in a reusable block, since one update then propagates to all cases that depend on it.
- Review negative coverage when requirements change. A new field or a changed limit invalidates old boundary values, so schedule that review as part of the requirement update, before outdated values reach the release.
Conclusion
Positive test cases prove the feature delivers what was promised, while negative test cases prove it holds together when input is wrong. Building both from the same requirement keeps the mapping clear and makes coverage easy to demonstrate. Teams that treat the negative side as a design task, supported by boundary analysis and risk ranking, ship fewer validation defects and spend less time reproducing production incidents.
Comments
Loading comments…